


Blog Insights
Deep insights on engineering, architecture, AI and building software that performs in the real world. Practical lessons from enterprise AI infrastructure projects.
Articles

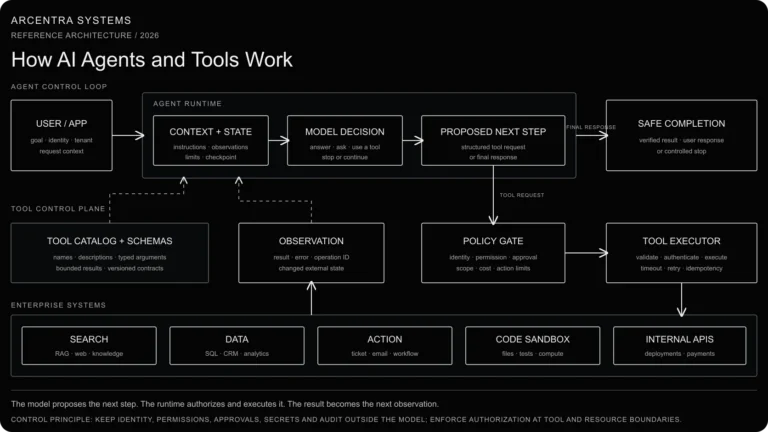
How AI Agents and Tools Work
An AI agent is a runtime loop around a language model and approved tools. Follow a task through model decisions, policy checks, execution, observations and safe completion.

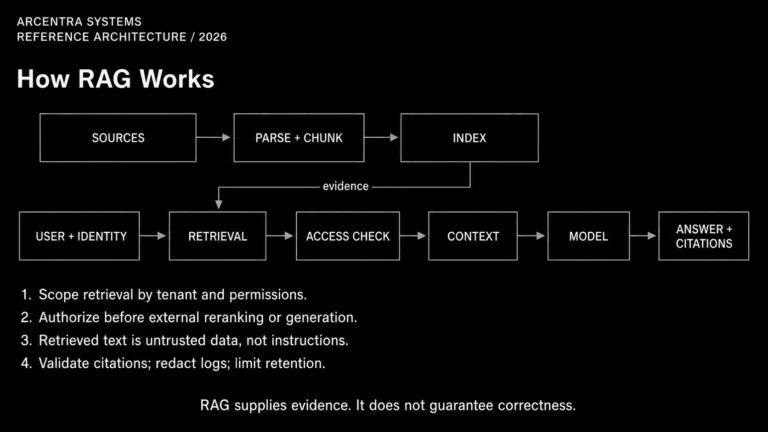
How RAG Works
RAG retrieves evidence before a language model answers. Follow an incident question through document preparation, permission checks, retrieval and a response that cites its sources.

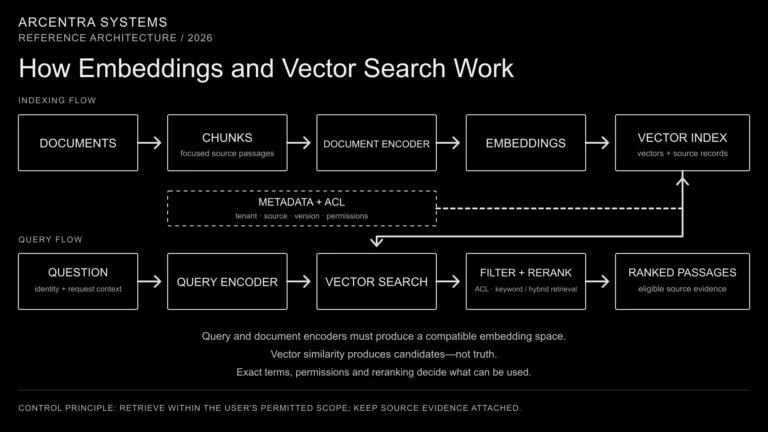
How Embeddings and Vector Search Work
How can a question about leaving a supplier agreement find a clause called termination for convenience? Follow the path from text to embeddings, vector search and ranked source passages.

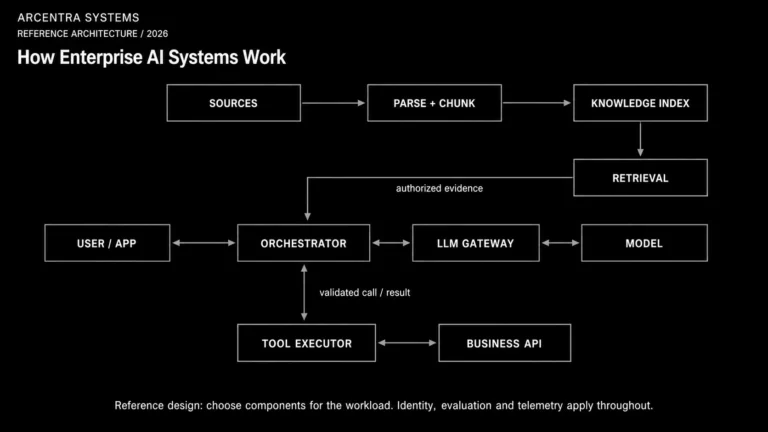
How Enterprise AI Systems Work
A language model is only one part of an enterprise AI system. Follow a question from the application through company data, access checks and retrieval to an answer or an approved action.

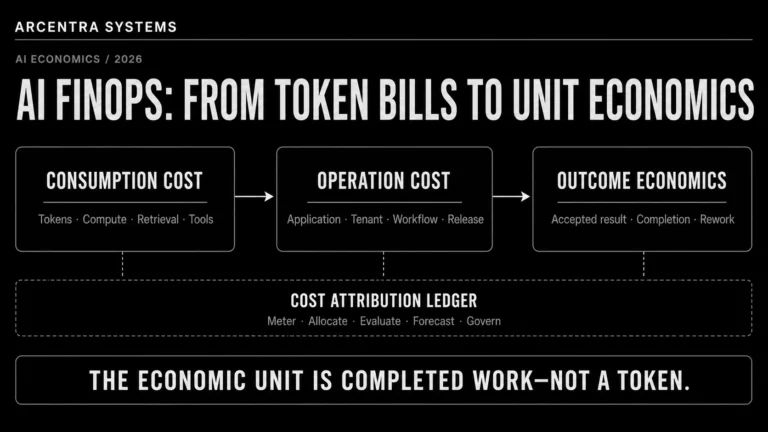
AI FinOps: From Token Bills to Unit Economics
The provider invoice is accurate and still does not tell you what the AI system costs. It can report input tokens, output tokens, provisioned throughput and vector-search usage. It cannot tell you whether a customer case was resolved, whether an agent completed the intended workflow or whether a cheaper model merely moved cost into retries […]

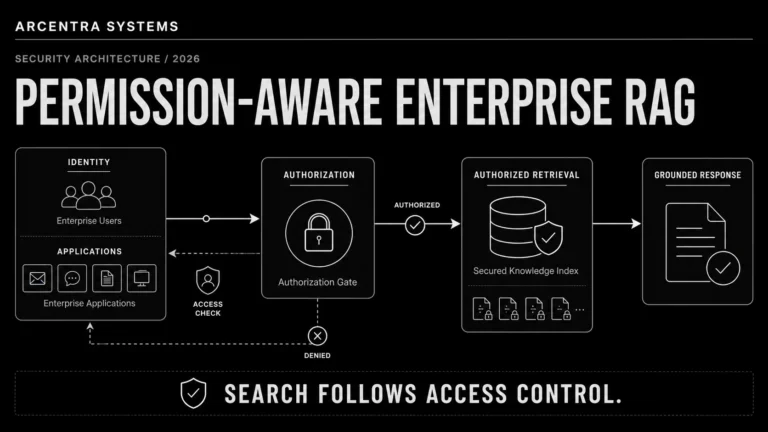
Enterprise RAG Is an Authorization Problem Before It Is a Search Problem
The most dangerous RAG failure is not a hallucination. It is a correct answer from a document the caller was never allowed to read. The model may quote the source accurately. Retrieval relevance may be excellent. Citations may resolve to real enterprise content. From a search perspective, the system worked. From a security perspective, it […]

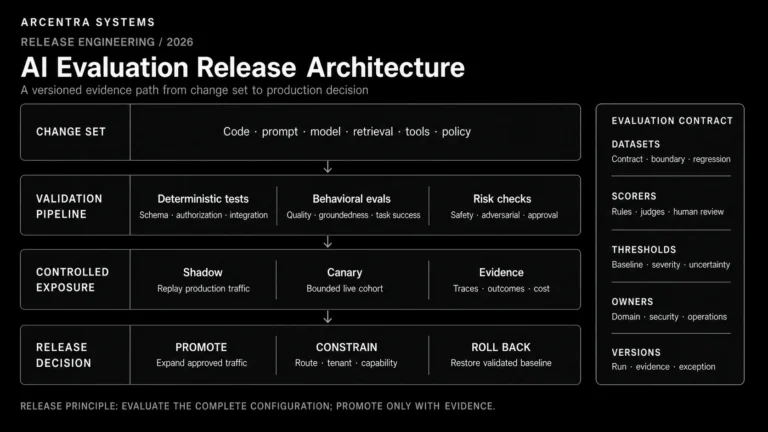
AI Evaluation Is a Release Engineering Problem
The easiest evaluation to pass is the one that cannot stop a release. Many AI teams have evaluation notebooks, scorecards and dashboards. Far fewer have an explicit answer to a harder question: what evidence is required before a new model, prompt, retrieval index or tool definition is allowed to receive production traffic? Without that decision […]

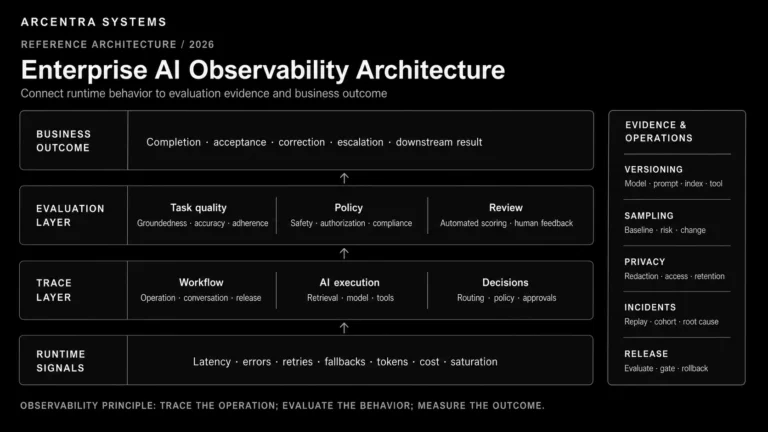
Enterprise AI Observability: What You Need to Measure Beyond Tokens and Latency
The dashboard is green. The incident is real. The model endpoint is available. P95 latency is inside the objective. Token consumption is stable. HTTP error rate has not moved. Yet users are correcting more answers, an agent is opening the wrong records, and a workflow that used to finish in two tool calls now needs […]

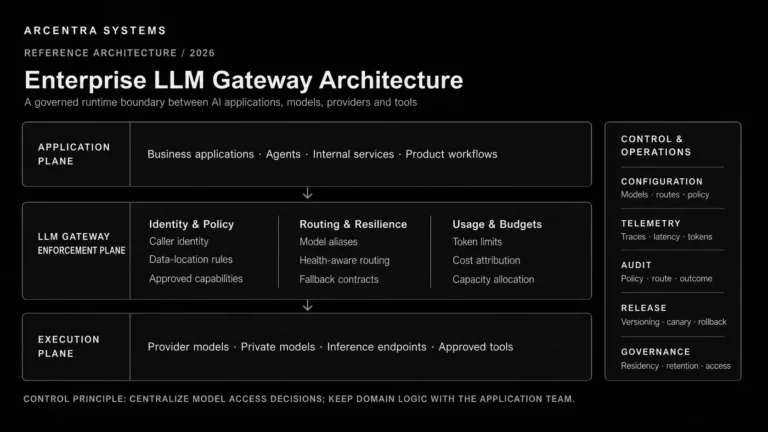
The Enterprise LLM Gateway Is the New Control Plane
The first application rarely needs an LLM gateway. A team can call a model provider directly, keep the API key in a secret store, add a timeout and ship. For one application, that is often the correct architecture. The trouble starts when the same pattern is repeated across a portfolio. One application retries every 429 […]

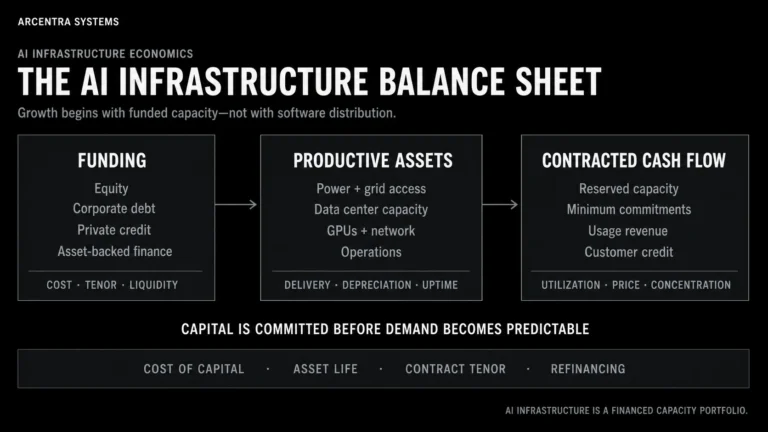
Why AI Infrastructure Looks More Like Banking Than Startups
AI infrastructure is usually described with the language of technology: GPU generations, cluster size, interconnect, tokens per second and model performance. Its economics are governed by a different vocabulary: capital cost, asset life, contract tenor, utilization, counterparty concentration, collateral value and refinancing. A software startup can add users before it has perfected monetization because distribution […]

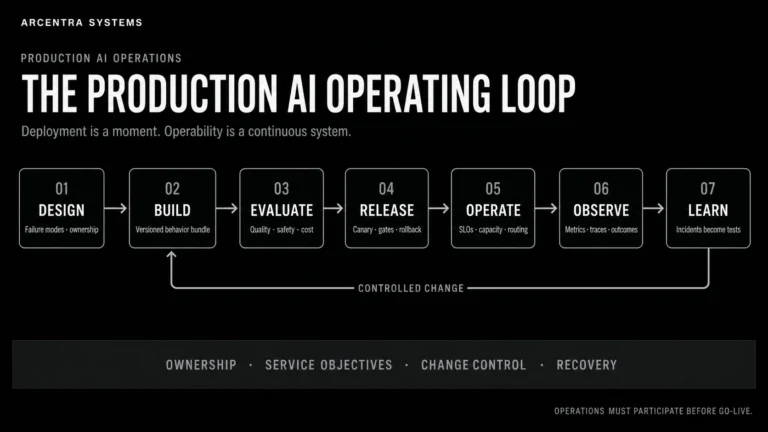
Building AI That Operations Can Actually Support
A successful deployment proves that an AI system can run under one configuration, with one set of dependencies, at one point in time. It does not prove that the system can be supported through provider throttling, prompt releases, stale retrieval indexes, tool failures, cost spikes or partial business transactions. That distinction is the boundary between […]

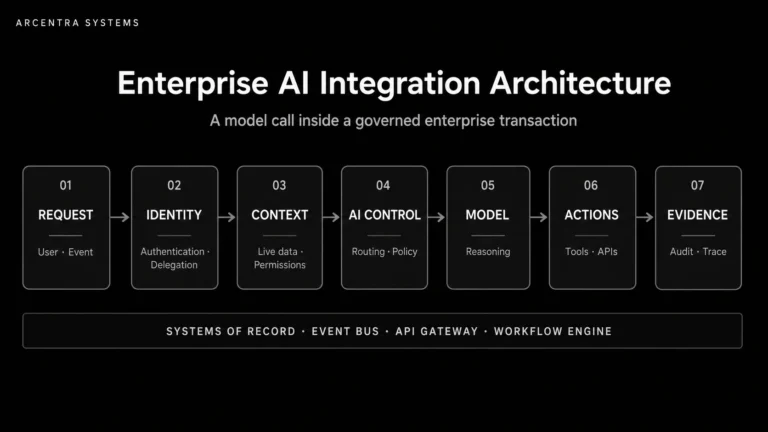
AI Integration Is Harder Than AI Itself
Enterprise AI projects are often framed as model-selection exercises. Teams compare reasoning quality, context windows, latency and price, then assume implementation begins once a provider has been chosen. In practice, a capable model is usually the easiest component to replace. The difficult work begins when an AI system must operate inside the enterprise: use live […]