

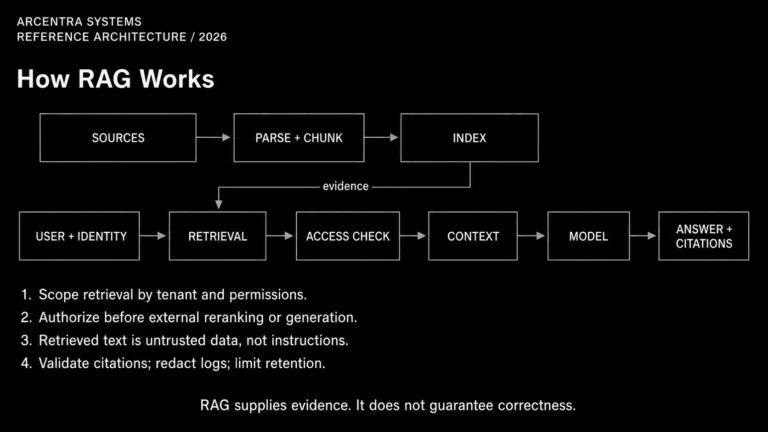
How RAG Works
RAG retrieves evidence before a language model answers. Follow an incident question through document preparation, permission checks, retrieval and a response that cites its sources.

RAG retrieves evidence before a language model answers. Follow an incident question through document preparation, permission checks, retrieval and a response that cites its sources.

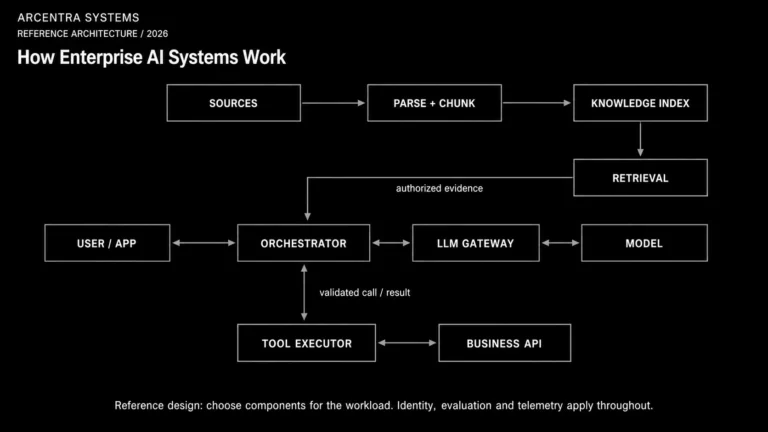
A language model is only one part of an enterprise AI system. Follow a question from the application through company data, access checks and retrieval to an answer or an approved action.

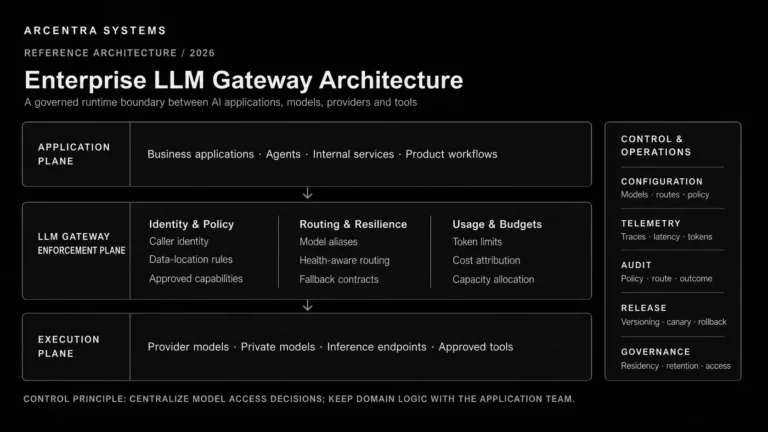
The first application rarely needs an LLM gateway. A team can call a model provider directly, keep the API key in a secret store, add a timeout and ship. For one application, that is often the correct architecture. The trouble starts when the same pattern is repeated across a portfolio. One application retries every 429 […]

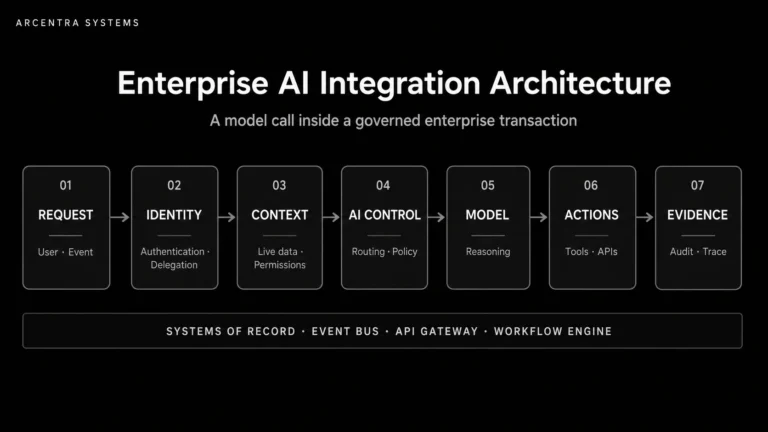
Enterprise AI projects are often framed as model-selection exercises. Teams compare reasoning quality, context windows, latency and price, then assume implementation begins once a provider has been chosen. In practice, a capable model is usually the easiest component to replace. The difficult work begins when an AI system must operate inside the enterprise: use live […]

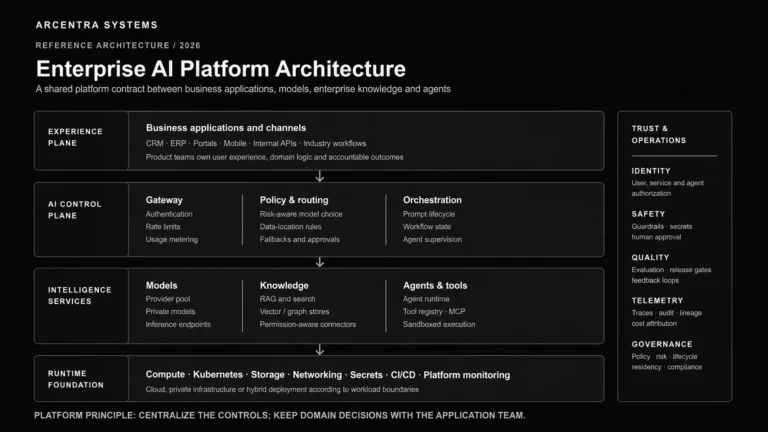
For two decades, the center of enterprise architecture was comparatively stable. ERP systems managed resources and transactions. CRM systems organized customer relationships. Integration platforms moved data between applications. Data warehouses consolidated analytics, while API gateways exposed internal services through consistent contracts. Those systems remain essential. But another shared layer is forming beside them: enterprise AI […]